How I Built an Orchestrated NL2SQL Pipeline That Scales with Complexity

Jul 12 2026

Natural language to SQL is one of those widely applicable problems that has not yet been solved with AI. On BIRD, the hardest public text-to-SQL benchmark, state-of-the-art single-pass systems top out around 75% execution accuracy. Human experts score 92.96%. The gap sits almost entirely on complex, multi-join, domain-rich questions where schema ambiguity and missing literals trip up every model.

This post walks through scale-analytics, a pipeline I built that reaches 89.67% execution accuracy on the test set by combining three axes of compute scaling — parallel synthesis, iterative refinement, and tournament selection — into a single orchestrated system. The goal was a production-grade design: observable, testable, model-agnostic, and runnable without proprietary RL-trained checkpoints.


The Core Insight: Scaling Compute, Not Parameters

This is a restatement of Sutton’s Bitter Lesson applied to inference: given a fixed model budget, the best lever is more compute at query time, not a bigger model or better prompts. Three scaling axes compound:

  • Parallel (width): generate many SQL candidates with diverse strategies and temperatures.
  • Sequential (depth): iteratively refine each candidate — fix syntax errors, then semantically revise.
  • Internal (quality): use RL-trained models that reason longer per token rather than stopping at the first plausible answer.

The architecture translates these three axes into four layers.


Architecture Overview: L0 to L3


L0 (offline, per-database)
  |
  +--> Light Schema  (markdown table + column descriptions)
  +--> DDL Schema    (CREATE TABLE for code-specialised models)
  +--> Cell Vector Store  (Chroma, all-MiniLM-L6-v2, one per DB)
  +--> Example Vector Store  (Chroma, question skeleton -> sql)
  +--> BM25 Index    (lexical fallback)

L1 (online, per query) -- Task Understanding
  KeywordSkeletonExtractor --> CellRetriever || ExampleRetriever

L2 (online) -- SQL Generation Scaling
  ReasoningGenerator || ICLGenerator x 3 strategies
  --> ExecutionBucketer --> SQLFixer (syntax) --> CritiqueAgent --> SQLRevisor (semantic)
  * critique-conditioned re-synthesis (up to 2 passes)

L3 (online) -- SQL Selection Scaling
  ExecutionBucketer --> TournamentArbiter --> ReasoningSelector
  --> Final SQL
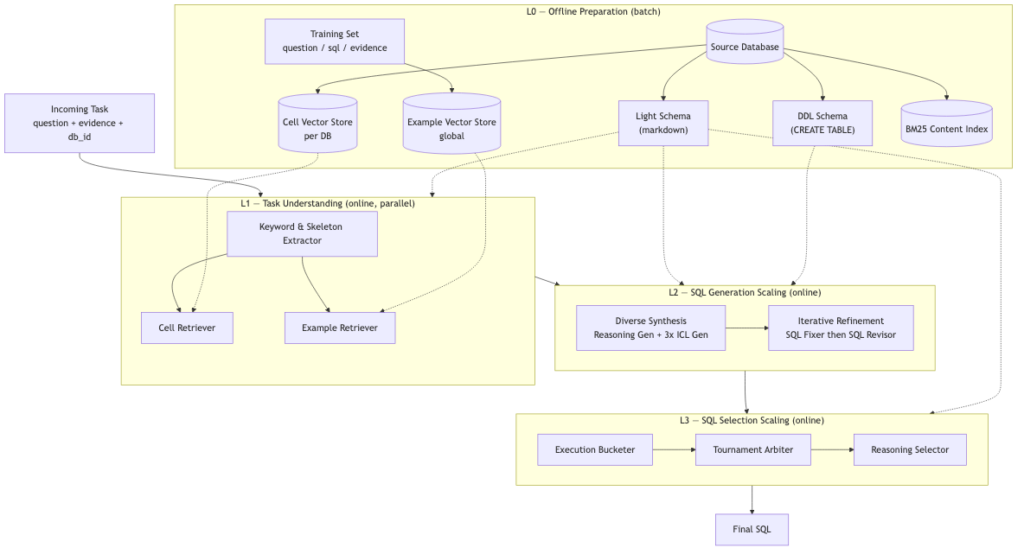

L0 runs once when database fields are updated. L1–L3 run on every incoming query. The total LLM call count per query is around fifteen in the default configuration — expensive, but the pipeline is designed to scale down for simple questions via a difficulty router that reduces k_icl and disables the tournament when the question is straightforward.


L1: Task Understanding

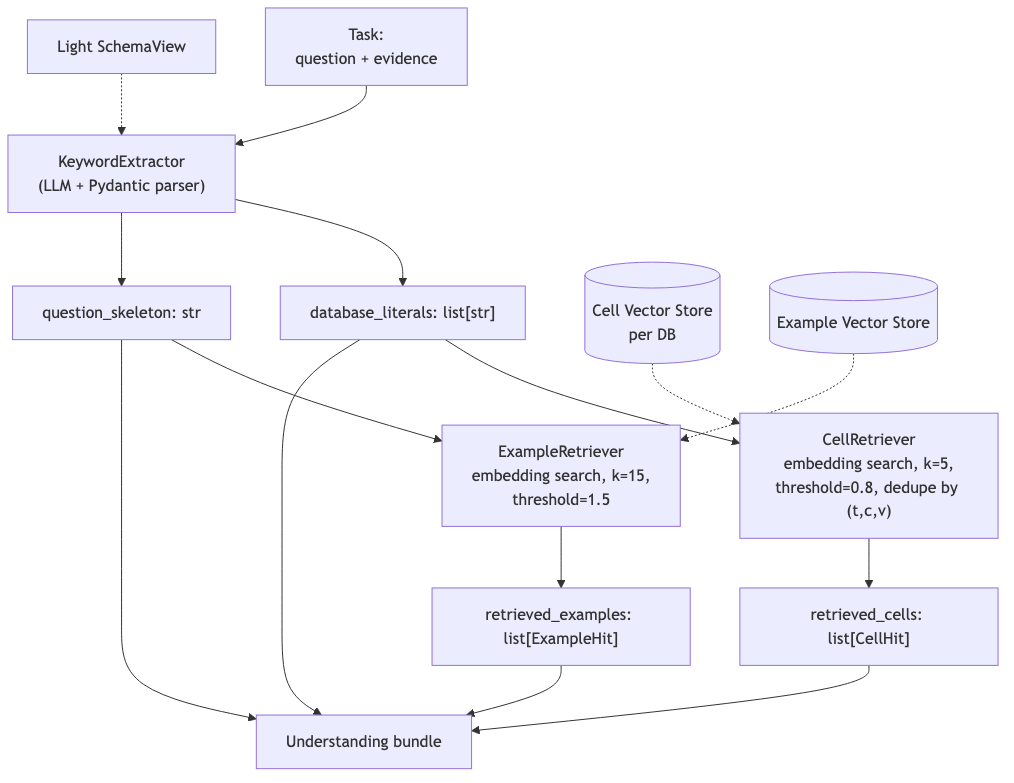
The first online stage extracts two things from the incoming question: database literals (exact cell values the SQL will need to match verbatim) and a question skeleton (a structural abstraction used to find similar few-shot examples).

These run in parallel via LangGraph’s Send primitive:

KeywordSkeletonExtractor (LLM, Gemini Flash T=0.2)
         |
         +--> literals --> CellRetriever (k=5, cosine threshold 0.8)
         `--> skeleton --> ExampleRetriever (k=15, threshold 1.5)

Cell retrieval searches a per-DB Chroma collection built from TEXT columns in the source database, filtered to exclude primary keys, IDs, emails, and strings over 256 characters. Example retrieval searches a global collection of training-set question skeletons to find structurally similar past questions with known-correct SQL.

Both retrievers return typed Pydantic objects (CellHit, ExampleHit) that the downstream generators consume directly — no string concatenation, no ad-hoc dicts.

L2: SQL Generation Scaling

This is where the diversity-then-refinement strategy plays out.

Diverse Synthesis

Two generator families run in parallel, each with a different schema view and a different prompting approach:

ReasoningGenerator — sees the DDL schema (CREATE TABLE with inline comments), no examples. Uses chain-of-thought inside <think>…</think> tags, then emits SQL inside <sql>…</sql>. Designed to slot in RL-trained reasoning checkpoints when available; falls back to DeepSeek-Coder-V2 or GPT-5 at high effort today.

ICLGenerator — sees the light markdown schema plus retrieved few-shot examples. Runs three sub-prompts in parallel to maximise diversity:

  • Direct: few-shot SQL completion.
  • Chain-of-Thought: reason in natural language, then emit SQL.
  • Question Decomposition: split into sub-questions, solve bottom-up, compose the final SQL.

Each of these generators outputs the commented SQL along with the reasoning in bullet points. Default configuration: 2 reasoning candidates + 2 × 3 ICL candidates = 8 total. Every candidate is executed immediately in the sandbox and tagged with its ExecutionResult.

Iterative Refinement

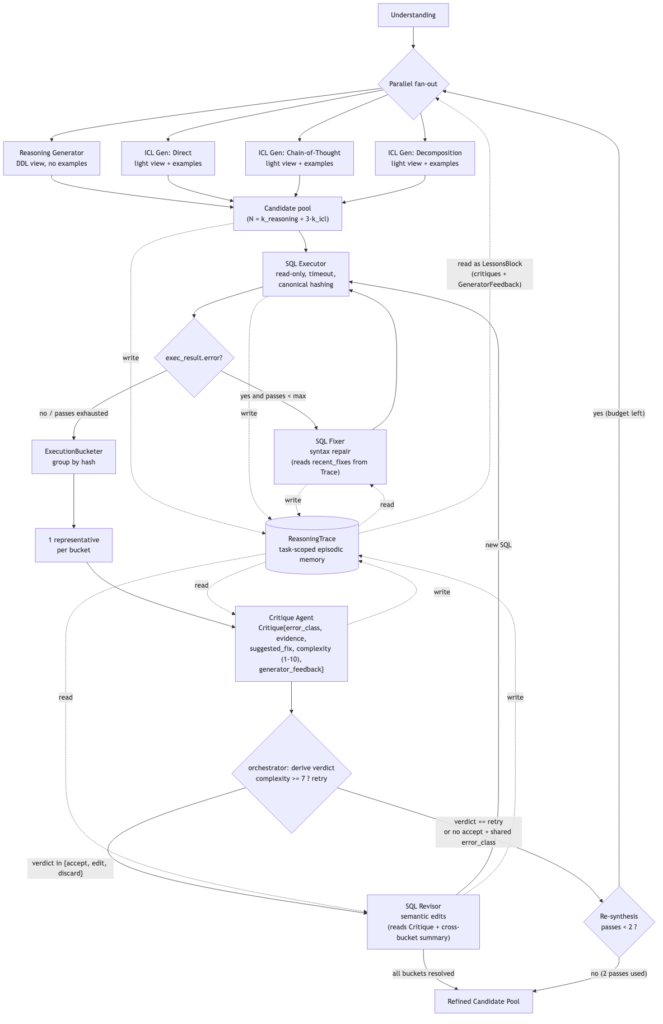
The refinement loop composes three agentic patterns so it learns within a single query from every generator’s reasoning, rather than treating each candidate as an independent draft:

  • Reflection — a dedicated CritiqueAgent separates generation from evaluation; structured feedback drives the next edit.
  • Memory Management — a task-scoped ReasoningTrace acts as an episodic scratchpad, recording every generator’s rationale, execution result, and critique for the duration of one query.
  • Learning and Adaptation — when the critique signals a framing problem that revision alone can’t fix, the orchestrator re-invokes the generators with accumulated lessons injected into their prompts.

The four components of the loop, in order:

ExecutionBucketer (no LLM) groups all candidates by ExecutionResult.hash. Candidates with errors or zero rows are flagged suspicious. Bucket metadata — size, producer mix, mean rationale length — is written to ReasoningTrace so downstream agents know which generators agreed.

SQLFixer (conditional) repairs candidates that errored. It reads ReasoningTrace.recent_fixes(producer) to avoid repeating a repair strategy that already failed on a sibling candidate from the same generator. Bounded at 2 passes; failed candidates are dropped from the tournament but kept in the trace.

CritiqueAgent (new) runs once per non-error bucket, before the revisor. It reads the bucket representative, its reasoning trace, and the rationales of every other generator — so it can contrast hypotheses, not just evaluate one candidate in isolation. It emits a typed Critique with:

  • error_class — a closed enum (wrong_join, missing_filter, wrong_aggregation, value_mismatch, evidence_ignored, other) so critiques are aggregatable across buckets and queries.
  • complexity — an integer 1–10 rating of how convoluted the reasoning required to answer the question is, based on the spread of generator rationales and the bucket representative’s structure. Anything ? 7 means editing alone is unlikely to converge.
  • suggested_fix — an actionable rewrite hint for the revisor.
  • generator_feedback — corrective material (correction or warning) for the generators on a re-synthesis pass, distinct from suggested_fix because it needs to be generic enough to seed multiple new candidates from different prompting strategies.

The retry verdict is derived by the orchestrator, not chosen by the LLM: if complexity >= 7, the orchestrator forces verdict = "retry" regardless of what the model wrote. This keeps the threshold a single source of truth in code and makes it unambiguously trace-grounded.

SQLRevisor runs on bucket representatives when the verdict is edit. It now receives the Critique (what is wrong) and a cross-bucket summary from ReasoningTrace (what other generators answered instead), so it is no longer reasoning blind about a single candidate. Bounded at 1–2 passes; any new SQL re-enters the loop from execution onward.

Critique-Conditioned Re-Synthesis

After each revisor pass, the orchestrator checks whether re-synthesis is warranted. It triggers a new generation round when either:

  1. Any bucket’s critique has complexity >= 7 (a retry verdict) — high-complexity questions are where framing errors happen at synthesis time, not editing time.
  2. No bucket was accepted and at least one error_class is shared across two or more buckets — meaning the generators systematically misread the same aspect of the question.

When triggered, the generators are re-invoked with a LessonsBlock injected into their prompts, assembled from ReasoningTrace:

Avoid: wrong_join — the join through order_items produces duplicate rows.
Prefer: join through orders directly.

## Corrections
- The join must go through orders, not order_items. [all generators]

## Warnings
- Be careful with NULL handling on customer.region. [icl/direct only]

New candidates re-enter the full loop (execution ? bucketing ? critique ? revision). Re-synthesis is capped at 2 passes (resynth_max_passes) and generates k_resynth = max(1, k_icl // 2) candidates per generator per pass. After 2 passes, L3 runs on whatever pool exists — the cap is non-negotiable to prevent reflection-loop runaway.

The ReasoningTrace itself is task-scoped and ephemeral: it lives for the duration of one query and is serialised into the final TaskContext for L3 and post-hoc analysis, but it is not long-term memory. Recurring lessons (distilled (skeleton, error_class, fix) triples) can optionally be written to a cross-task lesson store that augments L1 example retrieval on future queries — but that path is offline and does not affect the serving pipeline’s statefulness invariant.

L3: SQL Selection Scaling

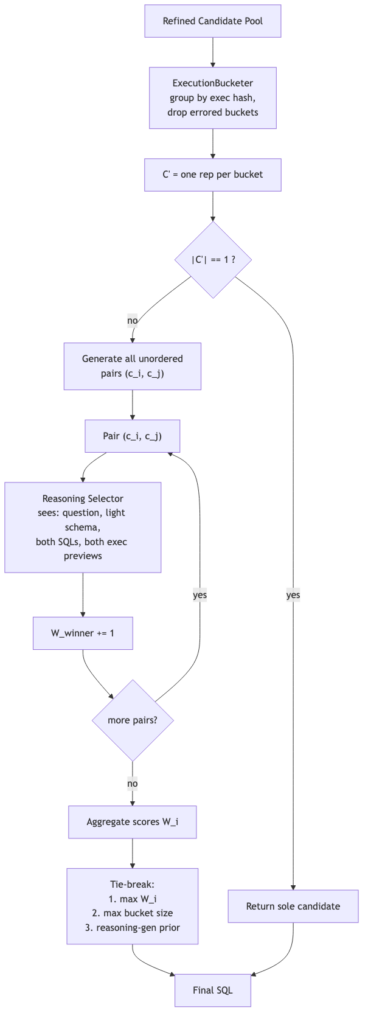
After refinement, you have a pool of candidates grouped by execution result hash. The tournament works like this:

  1. Take one representative per non-error bucket ? set C'.
  2. If |C'| == 1, return it immediately.
  3. Otherwise run pairwise round-robin: for every unordered pair (c_i, c_j), ask the ReasoningSelector which SQL better answers the question. It sees the question, the light schema, both SQL strings, and both execution previews.
  4. Rank by win count. Tie-break: (a) higher win count, (b) larger bucket (more generators agreed), (c) prefer the reasoning generator (empirically higher precision on simple/moderate questions).

Complexity is O(|C'|²) selector calls. In practice |C'| is 2–5 after bucketing, so the tournament costs 1–10 calls.

The Orchestrator: LangGraph as the Graph Runtime

The orchestrator is the only place where scaling lives as code. Agents are stateless; they have no idea about retries, fan-out width, or loop depth. The orchestrator’s ScalingConfig owns all of that:

class ScalingConfig(Frozen):
    k_reasoning: int = 2
    k_icl: int = 2                     # per sub-prompt
    k_resynth: int = 1                 # candidates per generator on re-synthesis (default max(1, k_icl//2))
    fixer_max_passes: int = 2
    refinement_max_passes: int = 1
    resynth_max_passes: int = 2        # critique-conditioned re-synthesis depth
    complexity_retry_threshold: int = 7  # Critique.complexity at or above which verdict is forced to "retry"
    tournament_enabled: bool = True
    global_timeout_s: int = 120
    token_budget: int = 200_000

I chose LangGraph over CrewAI, smolagents, Google ADK, and plain asyncio for one concrete reason: the pipeline’s structure — two fan-outs, two bounded loops, one tournament — maps directly onto LangGraph primitives. The Send primitive expresses per-candidate execution, per-bucket revision, and per-pair selector calls as first-class graph nodes rather than hand-rolled asyncio.gather blocks. Conditional edges express exec_result.error? ? fixer and refinement_passes_left? ? revisor without hand-rolled while loops. Checkpointers give us replay for free.

What we deliberately don’t take from LangGraph: its model wrappers. Every LLM call goes through our own model-adapter, and our AgentEvent schema is the authoritative lineage format — LangSmith and JSONL are sinks, not owners.


Data Contracts: Pydantic Frozen Models

Every type that crosses a module boundary is an immutable Pydantic v2 model. No dicts, no prompt strings, no ad-hoc tuples.

class Frozen(BaseModel):
    model_config = ConfigDict(frozen=True, extra="forbid", str_strip_whitespace=True)

class CandidateSQL(Frozen):
    sql: str
    producer: str                          # "reasoning/T=0.7", "icl/cot/T=1.0"
    rationale: Optional[str] = None
    exec_result: Optional[ExecutionResult] = None
    lineage: list[str] = Field(default_factory=list)  # ["gen", "fix", "revise:pass2"]

class ExecutionResult(Frozen):
    rows: tuple[tuple, ...]
    columns: tuple[str, ...]
    row_count: int = Field(ge=0)
    error: Optional[str] = None
    hash: str
    elapsed_ms: int = Field(ge=0)

frozen=True makes every contract hashable and safe to share across async tasks. extra="forbid" catches typos. ExecutionResult.hash is computed over a canonical form of the result set — sorted rows, normalised timestamps, float rounding to 6 decimal places — so that two syntactically different SQLs that return the same answer collapse into the same bucket.


The Execution Sandbox

Every candidate SQL is executed in a read-only sandbox before any LLM refinement or selection decision. This is load-bearing: bucketing, revision, and tournament selection all depend on the canonical hash.

Read-only enforcement is multi-layered:

  • SQLite: PRAGMA query_only = ON, opened with mode=ro URI.
  • A lightweight AST check rejects INSERT | UPDATE | DELETE | DROP | ALTER | ATTACH before execution reaches the driver.
  • Write violations raise ReadOnlyViolation synchronously; the connection is discarded, not returned to the pool.

The canonicalisation pipeline:

raw rows
  --> sort in-memory (stable tuple comparator; do NOT add ORDER BY to the SQL)
  --> normalise per cell (rstrip strings, round floats to 6dp, ISO-8601 timestamps, null sentinel)
  --> BLAKE2b hash over canonical JSON

Error results get an ERR: prefixed hash so they can never hash-collide with a successful result, and identical syntax errors across multiple candidates collapse into the same error bucket.


Observability: Three-Surface Tracing

Every agent call emits a typed AgentEvent following OpenTelemetry GenAI semantic conventions. Events are tagged with one of three surfaces:

SurfaceWhat it measuresExample agents
cognitivePlan quality, reasoning correctnessKeyword extractor, generators, selector
operationalTool-call reliabilitySQL executor, fixer
contextualRetrieval precisionCell retriever, example retriever

The evaluation harness derives per-surface metrics from this stream: Plan Adherence Rate, Tool Call Success Rate, Retrieval Precision, and Critic Adherence Rate (how often the Revisor actually adopts its own critique).

The Revisor’s reflection loop is a first-class event:

async with tracer.span("l2.sql_revisor", surface="cognitive", node="l2.revise") as span:
    verdict = await self._critique(candidate)
    await tracer.critique(
        "l2.sql_revisor",
        RevisionDelta(
            before_hash=candidate.exec_result.hash,
            after_hash=new_result.hash,
            verdict="revise",
            rationale="...",
        ),
    )
    span.set_output(revised_candidate)

This design lets you compute Critic Adherence Rate offline: for every case where the critique agent said “this needs a change,” did the new candidate actually produce a different result?

Events fan out to LangSmith (default) and a local JSONL file in parallel. If LangSmith is unreachable, the pipeline continues with the JSONL sink and logs a single warning.


DSPy for Prompt Compilation

Agents that the pipeline actually cares about optimising — the keyword extractor, the three ICL generator sub-prompts, the CritiqueAgent, the revisor, and the selector — are expressed as DSPy Signatures compiled against execution-grounded metrics.

The Revisor’s compilation metric is approximately:

def revisor_metric(example, pred, trace=None):
    result = sandbox.execute(pred.sql, db_id=example.db_id)
    if result.hash == example.gold_hash:
        return 1.0
    elif result.error is None:
        return 0.1
    return 0.0

The metric mirrors the same execution-grounded reward used to train RL-tuned reasoning models. When a stronger checkpoint becomes available, it replaces the compiled prompt behind the same DSPy Signature with zero orchestration changes — the signature is the contract, and either side (compiled prompt or RL model) can fulfill it.


Graceful Degradation

The pipeline fails hard in exactly one scenario: every generator produced zero candidates. Otherwise degradation is priority-ordered and monotonic:

  1. KeywordSkeletonExtractor fails –> continue with empty Understanding.
  2. CellRetriever or ExampleRetriever fails –> continue with empty list.
  3. One ICL sub-prompt fails –> continue with remaining generators.
  4. SQLFixer / SQLRevisor fails –> skip that pass, keep pre-refinement candidates.
  5. ReasoningSelector fails mid-tournament –> fall back to majority vote over bucket sizes.
  6. Budget or timeout exceeded –> return best-so-far candidate tagged degraded=True.

Every degradation fires a DecisionEvent with a label, confidence, and feature dict. The evaluation harness computes degraded_rate from the trace — so you can see whether degraded runs score proportionally worse and by how much.


Evaluation

The evaluation harness runs on a proprietary set of commonly asked questions in the healthcare domain about claims data. Primary metric is execution accuracy — does the candidate SQL produce the same result set as the gold SQL? Secondary is reward-based valid efficiency score, which weights correct queries by execution-time ratio vs gold.

The ablation table covers: drop the reasoning generator, drop ICL, drop the tournament (? self-consistency), drop refinement. Any fork of this codebase can compare directly.


References

  • Sutton (2019). The Bitter Lesson. incompleteideas.net
No responses yet

DynamoDB Free Tier Explained

Sep 27 2020

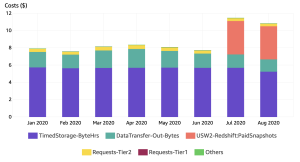
Recently AWS started charging for Redshift snapshots. I noticed an increase in my AWS bills and decided to dig into the reason. The cost explorer was quite nice, giving me a summary of spending over the past few months.
Screen Shot 2020-09-27 at 11.49.22 AM
Deleting my snapshot was an easy choice, since this data was used for analytics in my Redditor project and it only contained data up to 2016.

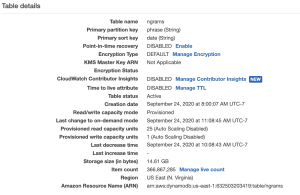
Next, I decided to look into whether I could reduce the DynamoDB monthly costs. This was a mystery to me, since AWS reported that the table only used up 14.6 GB. The free tier allowed up to 25 GB.
Screen Shot 2020-09-27 at 2.13.46 PM
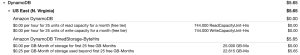
Yet, every month, I was getting billed for an extra 22 GB used. Screen Shot 2020-09-27 at 2.14.53 PM
After reading the detailed pricing documentation, I found the answer. Amazon explained in their pricing page that, “DynamoDB measures the size of your billable data by adding the raw byte size of the data you upload plus a per-item storage overhead of 100 bytes to account for indexing.” With some simple calculations, I arrived at the same range as my monthly costs:
Item count of 366,867,285 * 100 bytes = 36.6 GB
36.6 – (25 – 14.6) = 25 GB over the free tier limit

While the first free 25 GB was not enough for my use cases, it turned out that AWS allows up to 25 Write Capacity Units (WCUs) and 25 Read Capacity Units (RCUs) of provisioned capacity on the free tier, which is also barely enough for Redditor’s word frequency explorer. I decided to increase the read capacity to 25 RCUs, with each read unit allowing 4 KB of data transfer per second. A typical request to get the counts for word phrases over a period of several years returned about 100 KB of uncompressed data.
Screen Shot 2020-09-27 at 2.40.11 PM
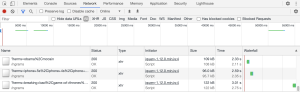
A quick calculation shows that a single request for ngram counts already uses up all of the RCUs alloted for a second!
100 KB / (4KB / s) = 1s (the request takes at least a second on DynamoDB)
As shown in the Chrome network performance tab, the requests took 2-3 seconds.

Solution

The solution for small projects is to use a MySQL key-value table where the time series data is stored in a single column.


    --------------------------------------------------------------------------------------------------------------------------------------------+
    | key                                   | series                                                                                            |
    +---------------------------------------+---------------------------------------------------------------------------------------------------+
    | example                               | 0,0,0,0,0,0,0,0,0,0,0,0,0,0,0,34,49,52,62,94,116,77,138,126,175,123...............................|
    +---------------------------------------+---------------------------------------------------------------------------------------------------+

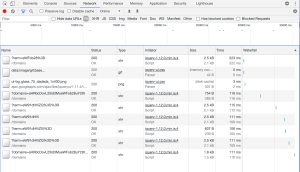
This works perfectly for read-only data where the series column does not need to be modified. I used this approach for storing web link frequency counts: https://github.com/yuguang/reddit-comments/tree/master/project. Using some simple Spark code, I filled in the data for missing months as 0 and imported the converted timeseries CSV into MySQL: https://github.com/yuguang/reddit-comments/blob/master/serving_optimization/optimize_timeseries.py. The result is that the response times are now under 150ms!
Screen Shot 2020-09-27 at 2.56.20 PM

No responses yet

Paper on DataMill

Nov 24 2015

The manuscript for the journal paper that I co-authored has been accepted for Software: Practice and Experience. The paper is titled DataMill: A Distributed Heterogeneous Infrastructure for Robust Experimentation and describes the second version of DataMill, a performance evaluation infrastructure, that I helped to build.

No responses yet

Merge Tags with django-taggit

Jan 01 2015

Today I cleaned up the database for Fiddle Salad and Python Fiddle. Both use the same Django back-end for code storage. While browsing tags, I noticed that often both CamelCase and lowercase spellings were used for tags. Since I was working on a tag suggest feature earlier this week, I decided to convert all tags to lowercase so that tag suggestions would not be redundant. An additional benefit is further normalization of the data. Fortunately, I found a fork of django-taggit, the Django app I used for tagging, that supported enforcing lowercase tags everywhere. Two management commands were already present for normalizing data, mergetags and lowercasetags. django-taggit had two fields for each tag, a name and slug. lowercasetags converted all tag names to their lowercase form. mergetags takes at least two tag slugs and merges all tags into a single destination tag. The result is that all associations are moved to a single tag. While mergetags is suitable for manually resolving redundant data, the number of tags on Fiddle Salad is too large. I wrote an command to automate this process:

[cc lang=”python”]
from django.core.management.base import BaseCommand, CommandError
from taggit.models import Tag, TaggedItem
from django.core.exceptions import ObjectDoesNotExist

class Command(BaseCommand):
help = ‘merges all tags automatically’

def merge(self, extra_slugs, dest_slug):
try:
dest_tag = Tag.objects.get(slug=dest_slug)
except ObjectDoesNotExist:
raise CommandError(‘Destination Tag “%s” does not exist’ % dest_slug)

for slug in extra_slugs:
try:
tag = Tag.objects.get(slug=slug)
except ObjectDoesNotExist:
raise CommandError(‘Tag “%s” does not exist’ % slug)

items = TaggedItem.objects.filter(tag=tag)
count = items.count()
for i, item in enumerate(items):
if i % 20 == 0:
self.stdout.write(‘Merging %s %d/%d\n’ % (slug, i+1, count))
obj = item.content_object
if not obj:
return
obj.tags.remove(tag)
obj.tags.add(dest_tag)
tag.delete()

self.stdout.write(‘Successfully merged tags into “%s”\n’ % dest_slug)

def handle(self, *args, **options):
for tag in Tag.objects.all():
if Tag.objects.filter(name=tag.name).count() > 1:
tags = Tag.objects.filter(name=tag.name).order_by(‘id’)
dest = tags[0].slug
extras = []
for tag in tags[1::]:
extras.append(tag.slug)
self.merge(extras, dest)
[/cc]
Because performance is not a concern for a single-time data processing script, I did not bother to optimize the queries nor run-time. This script would be useful for anyone who wants to normalize tags in the same manner, so it is in a git repository. Finally, I tested the new command on a clone of the production database.

bash-4.1$ python manage.py lowercasetags
Lowercasing 1/1621
Lowercasing 21/1621
.
.
.
Lowercasing 1621/1621
bash-4.1$ python manage.py mergealltags
Merging jquery_1 1/46
Merging jquery_1 21/46
Merging jquery_1 41/46
Successfully merged tags into "jquery"
Merging stylus_1 1/7
Successfully merged tags into "stylus"
Merging hello_1 1/10
Successfully merged tags into "hello"
Merging test_1 1/147
Merging test_1 21/147
Merging test_1 41/147
Merging test_1 61/147
Merging test_1 81/147
Merging test_1 101/147
Merging test_1 121/147
Merging test_1 141/147
Successfully merged tags into "test"
Merging me_1 1/2
Successfully merged tags into "me"
Merging no_1 1/5
Successfully merged tags into "no"
Merging one_1 1/16
Successfully merged tags into "one"
Merging things_1 1/3
Successfully merged tags into "things"
Merging learning_1 1/4
Successfully merged tags into "learning"
Successfully merged tags into "body"
Merging week-one_1 1/1
Successfully merged tags into "week-one"
Merging studio_1 1/33
Merging studio_1 21/33
Successfully merged tags into "studio"
Merging internet_1 1/36
Merging internet_1 21/36
Successfully merged tags into "internet"
Merging assignment_1 1/6
Successfully merged tags into "assignment"
Merging homework_1 1/6
Successfully merged tags into "homework"
Merging lessons_1 1/1
Successfully merged tags into "lessons"
Merging code_1 1/12
Merging tags_1 1/7
Successfully merged tags into "tags"
Merging two_1 1/6
Successfully merged tags into "two"
Merging salcedo_1 1/3
Successfully merged tags into "salcedo"
Merging page_1 1/15
Successfully merged tags into "page"
Merging music_1 1/4
Successfully merged tags into "music"
Merging table_1 1/7
Successfully merged tags into "table"
Merging band_1 1/9
Merging texas_1 1/1
Successfully merged tags into "texas"
Merging biography_1 1/2
Merging assignment-two_1 1/2
Successfully merged tags into "assignment-two"
Merging website_1 1/9
Merging a_1 1/2
Successfully merged tags into "a"
Merging words_1 1/1
Successfully merged tags into "words"
Merging section_1 1/2
Successfully merged tags into "section"
Merging header_1 1/1
Successfully merged tags into "header"
Merging ui_1 1/4
Successfully merged tags into "ui"
Merging first_1 1/8
Successfully merged tags into "first"
Merging random_1 1/1
Successfully merged tags into "random"
Merging internet-studio_1 1/5
Successfully merged tags into "internet-studio"
Merging angularjs_1 1/11
Successfully merged tags into "angularjs"
Merging i_1 1/2
Successfully merged tags into "i"
Merging lines_1 1/1
Successfully merged tags into "lines"
Merging row_1 1/1
Successfully merged tags into "row"
Merging alex-alpha_1 1/1
Successfully merged tags into "alex-alpha"
Merging assignment-one_1 1/2
Successfully merged tags into "assignment-one"
Merging google_1 1/1
Successfully merged tags into "google"
Merging man_1 1/4
Successfully merged tags into "man"
Merging nick_1 1/1
Successfully merged tags into "nick"
Merging cartoon_1 1/1
Successfully merged tags into "cartoon"
Merging batman_1 1/2
Successfully merged tags into "batman"
Merging code_1 1/7
Merging the_1 1/1
Successfully merged tags into "the"
Merging animation_1 1/2
Successfully merged tags into "animation"
Merging band_1 1/4
Merging assignment-one-of-three_1 1/2
Successfully merged tags into "assignment-one-of-three"
Merging status_1 1/1
Successfully merged tags into "status"
Merging python_1 1/2
Successfully merged tags into "python"
Merging cat_1 1/1
Successfully merged tags into "cat"
Merging none_1 1/7
Successfully merged tags into "none"
Merging adam_1 1/2
Successfully merged tags into "adam"
Merging school_1 1/3
Successfully merged tags into "school"
Merging website_1 1/9
Merging biography_1 1/2
Merging bootstrap_1 1/8
Successfully merged tags into "bootstrap"
Merging datamill_1 1/5
Successfully merged tags into "datamill"
Merging gentoo_1 1/2
Successfully merged tags into "gentoo"
Merging dobschal_1 1/1
Successfully merged tags into "dobschal"
Merging weimar_1 1/1
Successfully merged tags into "weimar"

When all went fine, I ran lowercasetags and mergealltags on both Fiddle Salad and Python Fiddle. Now I was really impressed with the results as I clicked through the tags on both sites. The tags on Fiddle Salad were much better organized as they were ordered by popularity. While looking through the tags, I noticed that “test” was among the top. I decided to add ‘test’ to the list of stopwords for django-taggit. These stopwords are removed during save so that they are not associated with new snippets.
Now that the tags are normalized, I am ready to move on and deploy tag suggestions.

One response so far

Getting E17 Back with Multiple Monitor Support

Jun 05 2014

I have been using e17 for about a year. I haven’t encountered any bugs, and it’s definitely stable enough for daily usage. On upgrading e17 earlier this week to 0.17.6, I found the monitors to be handled separately. I considered this to be a regression in the software. I installed the upstream development version 0.18.7, since it was in the Portage tree to see if it fixed the problems. Other people had the same multiple monitor or dual-monitor problems with e18. I played around with the settings to no avail. Installing 0.17.5 again by editing the 0.17.6 ebuild didn’t help.
I decided to install the old 0.17.5 ebuild which is no longer in the Pportage tree. Upon close examination, EFL (Enlightenment Foundation Libraries) in the recent ebuilds replaced the separate packages used in the 0.17.5.ebuild.
In the 0.17.5.ebuild:

RDEPEND="
pam? ( sys-libs/pam )
>=dev-libs/eet-1.7.9
>=dev-libs/efreet-1.7.9
>=dev-libs/eio-1.7.9
>=dev-libs/eina-1.7.9[mempool-chained-pool]
|| ( >=dev-libs/ecore-1.7.9[X,evas,inotify] >=dev-libs/ecore-1.7.9[xcb,evas,inotify] )
>=media-libs/edje-1.7.9
>=dev-libs/e_dbus-1.7.9[libnotify,udev?]
ukit? ( >=dev-libs/e_dbus-1.7.9[udev] )
enlightenment_modules_connman? ( >=dev-libs/e_dbus-1.7.9[connman] )
enlightenment_modules_shot? ( >=dev-libs/ecore-1.7.9[curl] )
|| ( >=media-libs/evas-1.7.9[eet,X,jpeg,png] >=media-libs/evas-1.7.9[eet,xcb,jpeg,png] )
>=dev-libs/eeze-1.7.9
emotion? ( >=media-libs/emotion-1.7.9 )
x11-libs/xcb-util-keysyms"

In the 0.17.6.ebuild:

RDEPEND="
pam? ( sys-libs/pam )
|| ( >=dev-libs/efl-1.8.4[X,eet,jpeg,png] >=dev-libs/efl-1.8.4[xcb,eet,jpeg,png] )
>=dev-libs/e_dbus-1.7.10
ukit? ( >=dev-libs/e_dbus-1.7.10[udev] )
x11-libs/xcb-util-keysyms"

I decided I had enough of the split screen methodology. One reason people don’t switch software is because they have to change the ways they interact with them. In my case, interacting with each monitor separately would lead to productivity loss while learning the new methodology and in the future. For example, the taskbar in the newer versions only show windows from one monitor. If I use two taskbars, I would have to keep track of where I put each window. User interfaces should get out of the way as much as possible so that users would not have to perform such unproductive chores.
Time to download the old ebuilds and rollback e17.

cd /usr/portage/x11-wm/enlightenment/
wget http://sources.gentoo.org/cgi-bin/viewvc.cgi/gentoo-x86/x11-wm/enlightenment/enlightenment-0.17.5.ebuild -O enlightenment-0.17.5.ebuild
ebuild enlightenment-0.17.5.ebuild digest
cd /usr/portage/x11-wm/enlightenment/
wget http://sources.gentoo.org/cgi-bin/viewvc.cgi/gentoo-x86/dev-libs/e_dbus/e_dbus-1.7.9.ebuild?revision=1.2 -O e_dbus-1.7.9.ebuild
ebuild e_dbus-1.7.9.ebuild digest
emerge -C dev-libs/efl
emerge =x11-wm/enlightenment-0.17.5

The general procedure is to download old ebuilds as necessary and remove packages that block other packages from being emerged. I went on to reinstall terminology, e17’s native terminal.

cd /usr/portage/x11-terms/terminology/
wget http://sources.gentoo.org/cgi-bin/viewvc.cgi/gentoo-x86/x11-terms/terminology/terminology-0.4.0_alpha1.ebuild?revision=1.2 -O terminology-0.4.0_alpha1.ebuild
ebuild terminology-0.4.0_alpha1.ebuild digest
emerge -pv =x11-terms/terminology-0.4.0_alpha1 | less
wget http://sources.gentoo.org/cgi-bin/viewvc.cgi/gentoo-x86/media-libs/elementary/elementary-1.7.9.ebuild -O ../../media-libs/elementary/elementary-1.7.9.ebuild
ebuild ../../media-libs/elementary/elementary-1.7.9.ebuild digest
emerge =media-libs/elementary-1.7.9
emerge -av =x11-terms/terminology-0.4.0_alpha1

Finally, to prevent future upgrades from undoing the work, mask newer versions of e17 and terminology in /etc/portage/package.mask/e17

>x11-wm/enlightenment-0.17.5
>x11-terms/terminology-0.4.0_alpha1
>=dev-libs/efl-1.9.4
>media-libs/elementary-1.7.9
>dev-libs/e_dbus-1.7.9

No responses yet

Computer Science Electives – Where do those theory classes pay off?

May 07 2014

When I finished my undergrad degree, I regretted taking CS 467. I spent about 80% of my coursework time on that class. Now that I see the same notation and set theory used in a statistics textbook I am reading, I would say the course was totally worth it. It would have helped if I had taken the assignments lightly, since the assignment questions were always a puzzle to students. The time would have been better spent working through examples in the textbook. Looking back at my elective courses, I am glad I didn’t take a CS elective that was mostly programming, such as CS 349. Classes like CS 360 enhance math skills which are helpful in graduate studies.

No responses yet

Btrfs RAID Setup

May 02 2014

We got a new server to be set up to build binary packages for DataMill. There was already RAID set up on it, and Linux automatically takes control of the disks. The first thing to do if you get errors such as unable to open /dev/sdb1: Device or resource busy or error checking /dev/sdc1 status: No such file or directory is to run fdisk to erase all partitions. Then reboot with parameters nodmraid nomdadm from your live CD, for example the System Rescue CD. After the reboot, I stopped the RAID controller and continued on with formatting.

root@sysresccd /root % cat /proc/mdstat
Personalities : [linear] [multipath] [raid0] [raid1] [raid6] [raid5] [raid4] [raid10]
md3 : active raid1 sda[0] sdb[1]
955692672 blocks [2/2] [UU]

unused devices:
root@sysresccd /root % mdadm --stop /dev/md3
mdadm: stopped /dev/md3
root@sysresccd /root % fdisk -l
Disk /dev/sda: 1000.2 GB, 1000204886016 bytes, 1953525168 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 4096 bytes
I/O size (minimum/optimal): 4096 bytes / 4096 bytes
Disk identifier: 0x6ac24fb3
Device Boot Start End Blocks Id System
Disk /dev/sdb: 1000.2 GB, 1000204886016 bytes, 1953525168 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 4096 bytes
I/O size (minimum/optimal): 4096 bytes / 4096 bytes
Disk identifier: 0x4de339dc
Device Boot Start End Blocks Id System
Disk /dev/sdc: 1000.2 GB, 1000204886016 bytes, 1953525168 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disk identifier: 0x52af89fe
Device Boot Start End Blocks Id System
Disk /dev/sdd: 15.5 GB, 15504900096 bytes, 30283008 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 512 bytes
I/O size (minimum/optimal): 512 bytes / 512 bytes
Disk identifier: 0x0001d5e6
Device Boot Start End Blocks Id System
/dev/sdd1 * 1 30283007 15141503+ c W95 FAT32 (LBA)
root@sysresccd /root % fdisk /dev/sda
The device presents a logical sector size that is smaller than
the physical sector size. Aligning to a physical sector (or optimal
I/O) size boundary is recommended, or performance may be impacted.
Welcome to fdisk (util-linux 2.22.2).
Changes will remain in memory only, until you decide to write them.
Be careful before using the write command.
Command (m for help): n
Partition type:
p primary (0 primary, 0 extended, 4 free)
e extended
Select (default p):
Using default response p
Partition number (1-4, default 1):
Using default value 1
First sector (2048-1953525167, default 2048):
Using default value 2048
Last sector, +sectors or +size{K,M,G} (2048-1953525167, default 1953525167): +500M
Partition 1 of type Linux and of size 500 MiB is set
Command (m for help): n
Partition type:
p primary (1 primary, 0 extended, 3 free)
e extended
Select (default p):
Using default response p
Partition number (1-4, default 2):
Using default value 2
First sector (1026048-1953525167, default 1026048):
Using default value 1026048
Last sector, +sectors or +size{K,M,G} (1026048-1953525167, default 1953525167):
+2G
Partition 2 of type Linux and of size 2 GiB is set
Command (m for help): n
Partition type:
p primary (2 primary, 0 extended, 2 free)
e extended
Select (default p):
Using default response p
Partition number (1-4, default 3):
Using default value 3
First sector (5220352-1953525167, default 5220352):
Using default value 5220352
Last sector, +sectors or +size{K,M,G} (5220352-1953525167, default 1953525167):
Using default value 1953525167
Partition 3 of type Linux and of size 929 GiB is set
Command (m for help): p
Disk /dev/sda: 1000.2 GB, 1000204886016 bytes, 1953525168 sectors
Units = sectors of 1 * 512 = 512 bytes
Sector size (logical/physical): 512 bytes / 4096 bytes
I/O size (minimum/optimal): 4096 bytes / 4096 bytes
Disk identifier: 0x6ac24fb3
Device Boot Start End Blocks Id System
/dev/sda1 2048 1026047 512000 83 Linux
/dev/sda2 1026048 5220351 2097152 83 Linux
/dev/sda3 5220352 1953525167 974152408 83 Linux
Command (m for help): t
Partition number (1-4): 2
Hex code (type L to list codes): 82
Changed system type of partition 2 to 82 (Linux swap / Solaris)
Command (m for help): w
The partition table has been altered!
Calling ioctl() to re-read partition table.
Syncing disks.
root@sysresccd /root % sfdisk -d /dev/sda > part_table
root@sysresccd /root % sfdisk /dev/sdb < part_table
Checking that no-one is using this disk right now ...
OK
Disk /dev/sdb: 121601 cylinders, 255 heads, 63 sectors/track
Old situation:
Units: cylinders of 8225280 bytes, blocks of 1024 bytes, counting from 0
Device Boot Start End #cyls #blocks Id System
/dev/sdb1 0 - 0 0 0 Empty
/dev/sdb2 0 - 0 0 0 Empty
/dev/sdb3 0 - 0 0 0 Empty
/dev/sdb4 0 - 0 0 0 Empty
New situation:
Units: sectors of 512 bytes, counting from 0
Device Boot Start End #sectors Id System
/dev/sdb1 2048 1026047 1024000 83 Linux
/dev/sdb2 1026048 5220351 4194304 82 Linux swap / Solaris
/dev/sdb3 5220352 1953525167 1948304816 83 Linux
/dev/sdb4 0 - 0 0 Empty
Warning: partition 1 does not end at a cylinder boundary
Warning: partition 2 does not start at a cylinder boundary
Warning: partition 2 does not end at a cylinder boundary
Warning: partition 3 does not start at a cylinder boundary
Warning: partition 3 does not end at a cylinder boundary
Warning: no primary partition is marked bootable (active)
This does not matter for LILO, but the DOS MBR will not boot this disk.
Successfully wrote the new partition table
Re-reading the partition table ...
If you created or changed a DOS partition, /dev/foo7, say, then use dd(1)
to zero the first 512 bytes: dd if=/dev/zero of=/dev/foo7 bs=512 count=1
(See fdisk(8).)
root@sysresccd /root % sfdisk /dev/sdc < part_table
Checking that no-one is using this disk right now ...
OK
Disk /dev/sdc: 121601 cylinders, 255 heads, 63 sectors/track
Old situation:
Units: cylinders of 8225280 bytes, blocks of 1024 bytes, counting from 0

Device Boot Start End #cyls #blocks Id System
/dev/sdc1 0 - 0 0 0 Empty
/dev/sdc2 0 - 0 0 0 Empty
/dev/sdc3 0 - 0 0 0 Empty
/dev/sdc4 0 - 0 0 0 Empty
New situation:
Units: sectors of 512 bytes, counting from 0

Device Boot Start End #sectors Id System
/dev/sdc1 2048 1026047 1024000 83 Linux
/dev/sdc2 1026048 5220351 4194304 82 Linux swap / Solaris
/dev/sdc3 5220352 1953525167 1948304816 83 Linux
/dev/sdc4 0 - 0 0 Empty
Warning: partition 1 does not end at a cylinder boundary
Warning: partition 2 does not start at a cylinder boundary
Warning: partition 2 does not end at a cylinder boundary
Warning: partition 3 does not start at a cylinder boundary
Warning: partition 3 does not end at a cylinder boundary
Warning: no primary partition is marked bootable (active)
This does not matter for LILO, but the DOS MBR will not boot this disk.
Successfully wrote the new partition table

Re-reading the partition table ...

If you created or changed a DOS partition, /dev/foo7, say, then use dd(1)
to zero the first 512 bytes: dd if=/dev/zero of=/dev/foo7 bs=512 count=1
(See fdisk(8).)
root@sysresccd /root % mkfs.btrfs -d raid5 /dev/sda1 /dev/sdb1 /dev/sdc1
/dev/sda1 appears to contain an existing filesystem (btrfs).
Error: Use the -f option to force overwrite.
root@sysresccd /root % mkfs.btrfs -f -d raid5 /dev/sda1 /dev/sdb1 /dev/sdc1
SMALL VOLUME: forcing mixed metadata/data groups
ERROR: With mixed block groups data and metadata profiles must be the same
root@sysresccd /root % mkfs.btrfs -f -d raid5 /dev/sda3 /dev/sdb3 /dev/sdc3
Error: unable to open /dev/sda3: Device or resource busy
root@sysresccd /root % cat /proc/mdstat
Personalities : [linear] [multipath] [raid0] [raid1] [raid6] [raid5] [raid4] [raid10]
md3 : active raid1 sdb3[1] sda3[0]
955692672 blocks [2/2] [UU]

unused devices:
root@sysresccd /root % mdadm --stop /dev/md3
mdadm: stopped /dev/md3
root@sysresccd /root % mkfs.btrfs -f -d raid5 /dev/sda3 /dev/sdb3 /dev/sdc3

WARNING! - Btrfs v3.12 IS EXPERIMENTAL
WARNING! - see http://btrfs.wiki.kernel.org before using

Turning ON incompat feature 'extref': increased hardlink limit per file to 65536Turning ON incompat feature 'raid56': raid56 extended format
adding device /dev/sdb3 id 2
adding device /dev/sdc3 id 3
fs created label (null) on /dev/sda3
nodesize 16384 leafsize 16384 sectorsize 4096 size 2.72TiB
Btrfs v3.12
root@sysresccd /root % mkfs.btrfs -f -O ^extref -d raid5 /dev/sda3 /dev/sdb3 /dev/sdc3

WARNING! - Btrfs v3.12 IS EXPERIMENTAL
WARNING! - see http://btrfs.wiki.kernel.org before using

Turning ON incompat feature 'raid56': raid56 extended format
adding device /dev/sdb3 id 2
adding device /dev/sdc3 id 3
fs created label (null) on /dev/sda3
nodesize 16384 leafsize 16384 sectorsize 4096 size 2.72TiB
Btrfs v3.12

When creating the btrfs volume for root, I turned off the extra hardlink feature with -O ^extref, and I ended up creating the /boot volume with

mkfs.btrfs -f /dev/sda1 /dev/sdb1 /dev/sdc1

to avoid the error. There are other options for creating a btrfs volume, such as specifying raid levels for data and metadata.

I mounted the btrfs volumes with -o compress=zlib during the install. To keep the compression when files are overwritten, these options must be included in /etc/fstab.

/dev/sda1 /boot btrfs compress=zlib,noauto,noatime 0 0
/dev/sda3 / btrfs compress=zlib,noatime 0 0
/dev/sda2 none swap sw 0 0
/dev/sdb2 none swap sw 0 0
/dev/sdc2 none swap sw 0 0

When compiling the kernel, RAID and LVM are not necessary since they are included in btrfs. LVM capabilities, such as growing a volume, are also available.
I used dracut to generate an initramfs that supports btrfs RAID boot with modifications to the configuration file /etc/dracut.conf.d.
# PUT YOUR CONFIG HERE OR IN separate files named *.conf
# in /etc/dracut.conf.d
# SEE man dracut.conf(5)

# Sample dracut config file

#logfile=/var/log/dracut.log
#fileloglvl=6

# Exact list of dracut modules to use. Modules not listed here are not going
# to be included. If you only want to add some optional modules use
# add_dracutmodules option instead.
#dracutmodules+=""

# dracut modules to omit
#omit_dracutmodules+=""

# dracut modules to add to the default
add_dracutmodules+="btrfs"

# additional kernel modules to the default
#add_drivers+=""

# list of kernel filesystem modules to be included in the generic initramfs
filesystems+="btrfs"

# build initrd only to boot current hardware
#hostonly="yes"
#

# install local /etc/mdadm.conf
mdadmconf="no"

# install local /etc/lvm/lvm.conf
lvmconf="no"

# A list of fsck tools to install. If it's not specified, module's hardcoded
# default is used, currently: "umount mount /sbin/fsck* xfs_db xfs_check
# xfs_repair e2fsck jfs_fsck reiserfsck btrfsck". The installation is
# opportunistic, so non-existing tools are just ignored.
#fscks=""

# inhibit installation of any fsck tools
nofscks="yes"

# mount / and /usr read-only by default
#ro_mnt="no"

# set the directory for temporary files
# default: /var/tmp
#tmpdir=/tmp
use_fstab="yes"

I then ran the command dracut --hostonly --force 'initramfs-genkernel-x86_64-3.12.13-gentoo' 3.12.13-gentoo which overwrote the file /boot/initramfs-genkernel-x86_64-3.12.13-gentoo.

No responses yet

Gentoo Oracle JDK on ARM

Mar 19 2014

Installing a JDK on ARM has several challenges. First, there is no binary icedtea for ARM. Second, building icedtea generates circular build time dependencies.
On my first attempt, I just ran the following commands:
emerge --autounmask-write virtual/jdk
dispatch-conf
emerge virtual/jdk

However, it soon met an error:

(controller) sabre2 ~ # cat /var/tmp/portage/dev-java/icedtea-bin-6.1.12.6-r1/temp/build.log
* Package: dev-java/icedtea-bin-6.1.12.6-r1
* Repository: gentoo
* Maintainer: java@gentoo.org
* USE: alsa arm elibc_glibc kernel_linux userland_GNU
* FEATURES: preserve-libs sandbox userpriv usersandbox
>>> Unpacking source...
* ERROR: dev-java/icedtea-bin-6.1.12.6-r1::gentoo failed (unpack phase):
* Nothing passed to the 'unpack' command
*
* Call stack:
* ebuild.sh, line 93: Called src_unpack
* environment, line 2546: Called unpack
* phase-helpers.sh, line 291: Called die
* The specific snippet of code:
* [ -z "$*" ] && die "Nothing passed to the 'unpack' command"
*
* If you need support, post the output of `emerge --info '=dev-java/icedtea-bin-6.1.12.6-r1::gentoo'`,
* the complete build log and the output of `emerge -pqv '=dev-java/icedtea-bin-6.1.12.6-r1::gentoo'`.
* The complete build log is located at '/var/tmp/portage/dev-java/icedtea-bin-6.1.12.6-r1/temp/build.log'.
* The ebuild environment file is located at '/var/tmp/portage/dev-java/icedtea-bin-6.1.12.6-r1/temp/environment'.
* Working directory: '/var/tmp/portage/dev-java/icedtea-bin-6.1.12.6-r1/work'
* S: '/var/tmp/portage/dev-java/icedtea-bin-6.1.12.6-r1/work/icedtea-bin-6.1.12.6'

Later, when I checked on gentoo-packages, it didn’t have an arm ebuild. Oracle has hardfloat and softfloat binary JDKs for ARM, so I went on to install them. They can be used to bootstrap an icedtea build.

# emerge -av dev-java/oracle-jdk-bin

* IMPORTANT: 1 news items need reading for repository 'gentoo'.
* Use eselect news to read news items.

* Last emerge --sync was 92d 19h 31m 27s ago.

These are the packages that would be merged, in order:

Calculating dependencies... done!
[ebuild N ] media-fonts/dejavu-2.33 USE="-X -fontforge" 4,767 kB
[ebuild N ] media-libs/freetype-2.4.11:2 USE="bindist bzip2 -X -auto-hinter -debug -doc -fontforge (-infinality) -static-libs -utils" 1,510 kB
[ebuild N ] virtual/ttf-fonts-1 0 kB
[ebuild N ] media-libs/fontconfig-2.10.92:1.0 USE="-doc -static-libs" 1,490 kB
[ebuild N ] app-admin/eselect-fontconfig-1.0 0 kB
[ebuild N F *] dev-java/oracle-jdk-bin-1.7.0.40:1.7 USE="fontconfig -X -alsa
-derby -doc -examples -jce -nsplugin -pax_kernel -source" 138,494 kB

Total: 6 packages (6 new), Size of downloads: 146,260 kB
Fetch Restriction: 1 package (1 unsatisfied)

Fetch instructions for dev-java/oracle-jdk-bin-1.7.0.40:
*
* Oracle requires you to download the needed files manually after
* accepting their license through a javascript capable web browser.
*
* Download the following files:
* jdk-7u40-linux-arm-vfp-sflt.tar.gz
* jdk-7u40-linux-arm-vfp-hflt.tar.gz
* at 'http://www.oracle.com/technetwork/java/javase/downloads/jdk7-downloads-1880260.html'
* and move them to '/distfiles'
*

The following keyword changes are necessary to proceed:
(see "package.accept_keywords" in the portage(5) man page for more details)
# required by dev-java/oracle-jdk-bin (argument)
=dev-java/oracle-jdk-bin-1.7.0.40 **

The following license changes are necessary to proceed:
(see "package.license" in the portage(5) man page for more details)
# required by dev-java/oracle-jdk-bin (argument)
>=dev-java/oracle-jdk-bin-1.7.0.40 Oracle-BCLA-JavaSE

NOTE: The --autounmask-keep-masks option will prevent emerge
from creating package.unmask or ** keyword changes.

Use --autounmask-write to write changes to config files (honoring
CONFIG_PROTECT). Carefully examine the list of proposed changes,
paying special attention to mask or keyword changes that may expose
experimental or unstable packages.

You may not have a browser installed on your ARM board, so I suggest just uploading the Oracle tarballs to a server and using wget to download them.
To fix the control panel error when you don’t have a desktop environment installed, you need to remove lines from the ebuild and digest it.

vim /usr/portage/dev-java/oracle-jdk-bin/oracle-jdk-bin-1.7.0.40.ebuild

These lines need to be removed:
newicon jre/lib/desktop/icons/hicolor/48x48/apps/sun-jcontrol.png \
sun-jcontrol-${PN}-${SLOT}.png || die
sed -e "s#Name=.*#Name=Java Control Panel for Oracle JDK ${SLOT}#" \
-e "s#Exec=.*#Exec=/opt/${P}/jre/bin/jcontrol#" \
-e "s#Icon=.*#Icon=sun-jcontrol-${PN}-${SLOT}#" \
-e "s#Application;##" \
-e "/Encoding/d" \
jre/lib/desktop/applications/sun_java.desktop \
> "${T}"/jcontrol-${PN}-${SLOT}.desktop || die
domenu "${T}"/jcontrol-${PN}-${SLOT}.desktop

Once removed, generate the manifest for it.
ebuild /usr/portage/dev-java/oracle-jdk-bin/oracle-jdk-bin-1.7.0.40.ebuild digest
If you run emerge dev-java/oracle-jdk-bin, it will succeed.

No responses yet

Gentoo on SABRE Lite

Jan 23 2014

I recently received several SABRE Lite BD-SL-i.MX6 boards for running ARM benchmarks on DataMill. To install Gentoo on it, you need a USB-to-serial cable converter. It came with a 4GB SD card, which is large enough to get you started.
Overview of the installation:

  • Reset board and format SD card (optional)
  • Compile kernel with btrfs support (optional)
  • Copy boot script and kernel
  • Extract stage3 and portage snapshot
  • Configure the install
  • Backup and clone (optional)

Reset board and format SD card

When I first tried to boot images extracted to the SD card on the board, it always got stuck at the U-Boot prompt. It turned out that there were environment variables left over from previous uses for these boards. Here is the way to reset board variables:

U-Boot > run clearenv
U-Boot > reset

After I managed to boot Linux images on it, I went onto formatting the card for a Gentoo install. I used sfdisk so that formatting can be scripted with a file which I saved as mmc_partitions:

# partition table of /dev/sdd
unit: sectors

/dev/sdd1 : start= 2048, size= 102400, Id=83
/dev/sdd2 : start= 104448, size= 7669760, Id=83
/dev/sdd3 : start= 0, size= 0, Id= 0
/dev/sdd4 : start= 0, size= 0, Id= 0

I formatted the second partition as btrfs so that compression could be used on the small SD card. You may want to format it as ext3 to save time. If you have problems getting it to boot, check to make sure your btrfs-progs are not newer than the btrfs version the kernel is built to support. sys-fs/btrfs-progs-0.20_rc1 worked for the January 2014 kernel source.

# sfdisk -f /dev/sdd < mmc_partitions # mkfs.btrfs -f /dev/sdd2 && mkfs.ext2 /dev/sdd1

Compile kernel with btrfs support

The git tree for the kernel is available at https://github.com/boundarydevices/linux-imx6/. There are two main branches, one for Android and one for non-Android. Use the most recent one for non-Android.

# wget https://github.com/boundarydevices/linux-imx6/archive/boundary-imx_3.0.35_4.1.0.zip
# unzip boundary-imx_3.0.35_4.1.0.zip
# cd linux-imx6-boundary-imx_3.0.35_4.0.0
# make ARCH=arm imx6_defconfig
# vim .config

Make the following changes to the kernel config:

CONFIG_DEVTMPFS=y
CONFIG_BTRFS_FS=y
CONFIG_CRYPTO_CRC32C=y
CONFIG_LIBCRC32C=y

Gentoo requires a devtmpfs filesystem to mount at /dev while selecting btrfs also selects LIBCRC32C. The CRC32c CRC algorithm is used by btrfs for checksums.
Now cross compile the kernel

# make -j9 ARCH=arm CROSS_COMPILE=armv7a-unknown-linux-gnueabi- uImage

Copy boot script and kernel

Download 6x_bootscript-20121110 available from a blog post and rename it 6x_bootscript. Get the kernel from one of the i.MX6 builds if you decided to skip building it.

# mount -o compress=zlib /dev/sdd2 /mnt/p1 && mkdir /mnt/p1/boot && mount /dev/sdd1 /mnt/p1/boot
# cp 6x_bootscript /mnt/p1/boot
# cp uImage /mnt/p1/boot

uImage is located in /usr/src/linux/arch/arm/boot if you compiled the kernel.

Extract stage3 and portage snapshot

Download the latest stage3 tarball and extract it
tar xjpf stage3-armv7a*.tar.bz2 -C /mnt/p1
BD-SL-i.MX6 with serial cable
If you get errors trying to run emerge --sync, it is because downloading the portage tree is not optional unlike other guides indicate. Simply download it from your nearest mirror and extract it

# tar xjpf portage-latest.tar.bz2 -C /mnt/p1/usr

Configure the install

If you compiled the kernel with btrfs, edit /mnt/p1/etc/fstab file so that zlib compression is enabled

/dev/mmcblk0p1 /boot ext2 noatime 0 1
/dev/mmcblk0p2 / btrfs noatime,compress=zlib
0 1

Set kernel boot argument in /mnt/p1/etc/inittab. Change the console= argument to ttymxc1. eg "$bootargs console=ttymxc1,115200 vmalloc=400M consoleblank=0 rootwait"
The rest of the process is the same as for other ARM boards, such as the Trimslice. The guide for it is available at http://dev.gentoo.org/~armin76/arm/trimslice/install.xml.
4 SABRE Lite i.mx6 Development Boards on the benchmark rack

Backup and clone

First make the backup in a folder
cd /backups
tar -cvpzf backup.tar.gz /mnt/p1/

After unmounting the SD card and testing it on the device, put in a new one and clone it with the following commands

sfdisk -f /dev/sdd < mmc_partitions mkfs.btrfs -f /dev/sdd2 && mkfs.ext2 -FF /dev/sdd1 mount -o compress=zlib /dev/sdd2 /mnt/p1 && mkdir /mnt/p1/boot && mount /dev/sdd1 /mnt/p1/boot tar xzpf backup.tar.gz -C /mnt/p1 vim /mnt/p1/etc/conf.d/hostname umount /mnt/p1/boot && umount /mnt/p1

The Funtoo ARM Guide has up to date sections on setting the root password and using swclock. If you decide to use swclock, update the last shutdown time to set the clock with touch /tmp/mnt/p1/lib/rc/cache/shutdowntime after extracting the tarball.

No responses yet

YouTube popularity of my IDE videos

Nov 29 2013

The recent video I made for Python Fiddle didn’t prove to be a hit with on 60 views so far, but the one for the JavaScript IDE has been on the top or second place in referrals for Fiddle Salad. One explanation would be YouTube’s video ranking algorithm takes into account community factors such as subscribed channels and the videos in your channel.
The number of visitors to my site for Wijmo Books is also disappointing but almost to be expected. At least the site was a lot of fun to build and still looks spiff.

No responses yet

Older »